Performance over time
How ComposableTuringIDModels's benchmark suites have moved across recent revisions: an overall summary across the package first, then one section per suite.
Summary
Each benchmark suite's headline timing across recent revisions.
| Suite | Median ratio | Trend | Status |
|---|---|---|---|
| AD gradients | 0.99 | → | ok |
| Model evaluation | 1.01 | → | ok |
| Sampling | 0.98 | ↘ | ok |
| time_to_load | 1.0 | → | ok |
Ratio: latest vs oldest shown revision (1.00 = no change, higher = slower/larger). ⚠ reg = at/above the regression threshold.
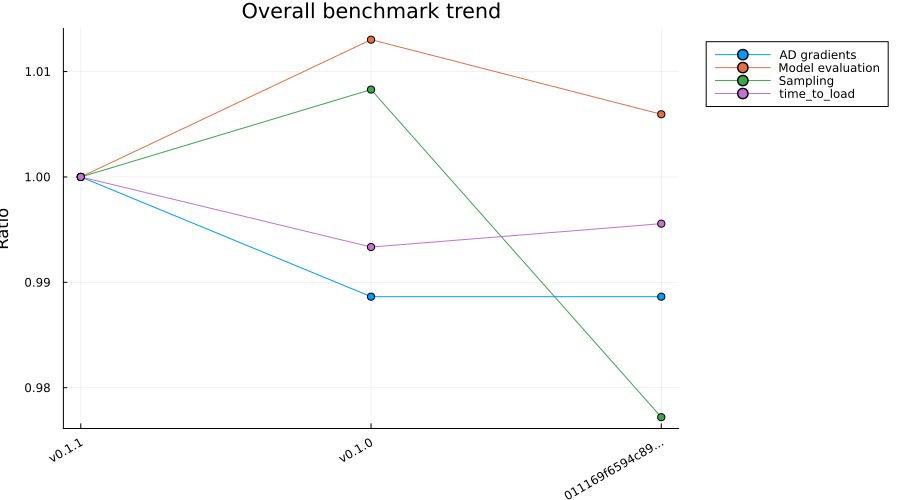
Tables below show the most recent 3 revisions, columns labelled by commit date.
AD gradients
Time
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| AR latent logjoint/ForwardDiff | 14.1 ± 22 μs | 11.1 ± 3.4 μs | 12 ± 22 μs |
| AR latent logjoint/Mooncake reverse | 8.81 ± 2.6 μs | 8.94 ± 2.7 μs | 8.87 ± 2.7 μs |
| AR latent logjoint/ReverseDiff (tape) | 0.0508 ± 0.0087 ms | 0.0507 ± 0.0018 ms | 0.051 ± 0.0087 ms |
| DirectInfections+Poisson posterior/Enzyme reverse | 0.0709 ± 0.00085 ms | 0.0705 ± 0.00085 ms | 0.0703 ± 0.00081 ms |
| DirectInfections+Poisson posterior/ForwardDiff | 0.232 ± 0.028 ms | 0.21 ± 0.026 ms | 0.206 ± 0.014 ms |
| DirectInfections+Poisson posterior/Mooncake reverse | 0.0798 ± 0.0013 ms | 0.0799 ± 0.0013 ms | 0.0786 ± 0.0012 ms |
| DirectInfections+Poisson posterior/ReverseDiff (tape) | 0.176 ± 0.025 ms | 0.174 ± 0.023 ms | 0.174 ± 0.023 ms |
Memory
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| AR latent logjoint/ForwardDiff | 0.056 k allocs: 0.0508 MB | 0.056 k allocs: 0.0508 MB | 0.056 k allocs: 0.0508 MB |
| AR latent logjoint/Mooncake reverse | 0.04 k allocs: 4.98 kB | 0.04 k allocs: 4.98 kB | 0.04 k allocs: 4.98 kB |
| AR latent logjoint/ReverseDiff (tape) | 0.775 k allocs: 0.0319 MB | 0.775 k allocs: 0.0319 MB | 0.775 k allocs: 0.0319 MB |
| DirectInfections+Poisson posterior/Enzyme reverse | 0.242 k allocs: 12.3 kB | 0.242 k allocs: 12.3 kB | 0.242 k allocs: 12.3 kB |
| DirectInfections+Poisson posterior/ForwardDiff | 0.68 k allocs: 0.0835 MB | 0.68 k allocs: 0.0835 MB | 0.68 k allocs: 0.0835 MB |
| DirectInfections+Poisson posterior/Mooncake reverse | 0.32 k allocs: 15.5 kB | 0.32 k allocs: 15.5 kB | 0.32 k allocs: 15.5 kB |
| DirectInfections+Poisson posterior/ReverseDiff (tape) | 1.65 k allocs: 0.0654 MB | 1.65 k allocs: 0.0654 MB | 1.65 k allocs: 0.0654 MB |
Model evaluation
Time
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| AR latent/forward | 0.633 ± 0.078 μs | 0.643 ± 0.1 μs | 0.639 ± 0.09 μs |
| AR latent/rand | 0.883 ± 1.2 μs | 0.865 ± 1.2 μs | 1.23 ± 1.2 μs |
| DirectInfections+Poisson/forward | 0.0683 ± 0.00094 ms | 0.0678 ± 0.0012 ms | 0.0663 ± 0.00096 ms |
| DirectInfections+Poisson/rand | 0.0666 ± 0.00099 ms | 0.0666 ± 0.0013 ms | 0.0653 ± 0.00096 ms |
| RandomWalk latent/forward | 1.28 ± 0.75 μs | 1.28 ± 0.72 μs | 1.29 ± 0.75 μs |
| RandomWalk latent/rand | 1.45 ± 0.97 μs | 1.45 ± 0.96 μs | 1.48 ± 0.98 μs |
| Renewal+NegativeBinomial/forward | 0.0733 ± 0.0011 ms | 0.0725 ± 0.001 ms | 0.0715 ± 0.001 ms |
| Renewal+NegativeBinomial/rand | 0.0713 ± 0.0013 ms | 0.0699 ± 0.0013 ms | 0.0684 ± 0.0012 ms |
Memory
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| AR latent/forward | 20 allocs: 2.41 kB | 20 allocs: 2.41 kB | 20 allocs: 2.41 kB |
| AR latent/rand | 22 allocs: 2.83 kB | 22 allocs: 2.83 kB | 22 allocs: 2.83 kB |
| DirectInfections+Poisson/forward | 0.35 k allocs: 15.8 kB | 0.35 k allocs: 15.8 kB | 0.35 k allocs: 15.8 kB |
| DirectInfections+Poisson/rand | 0.349 k allocs: 15.1 kB | 0.349 k allocs: 15.1 kB | 0.349 k allocs: 15.1 kB |
| RandomWalk latent/forward | 16 allocs: 1.83 kB | 16 allocs: 1.83 kB | 16 allocs: 1.83 kB |
| RandomWalk latent/rand | 15 allocs: 2.05 kB | 15 allocs: 2.05 kB | 15 allocs: 2.05 kB |
| Renewal+NegativeBinomial/forward | 0.57 k allocs: 23.7 kB | 0.57 k allocs: 23.7 kB | 0.57 k allocs: 23.7 kB |
| Renewal+NegativeBinomial/rand | 0.567 k allocs: 23 kB | 0.567 k allocs: 23 kB | 0.567 k allocs: 23 kB |
Sampling
Time
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| NUTS (DirectInfections+Poisson, 50 draws) | 0.965 ± 0.037 s | 0.973 ± 0.047 s | 0.943 ± 0.037 s |
Memory
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| NUTS (DirectInfections+Poisson, 50 draws) | 2.99 M allocs: 0.371 GB | 2.99 M allocs: 0.371 GB | 2.99 M allocs: 0.371 GB |
time_to_load
Time
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| time_to_load | 4.51 ± 0.11 s | 4.48 ± 0.031 s | 4.49 ± 0.02 s |
Memory
| Benchmark | v0.1.1 | v0.1.0 | 011169f6594c89... |
|---|---|---|---|
| time_to_load | 0.149 k allocs: 11.2 kB | 0.149 k allocs: 11.2 kB | 0.149 k allocs: 11.2 kB |
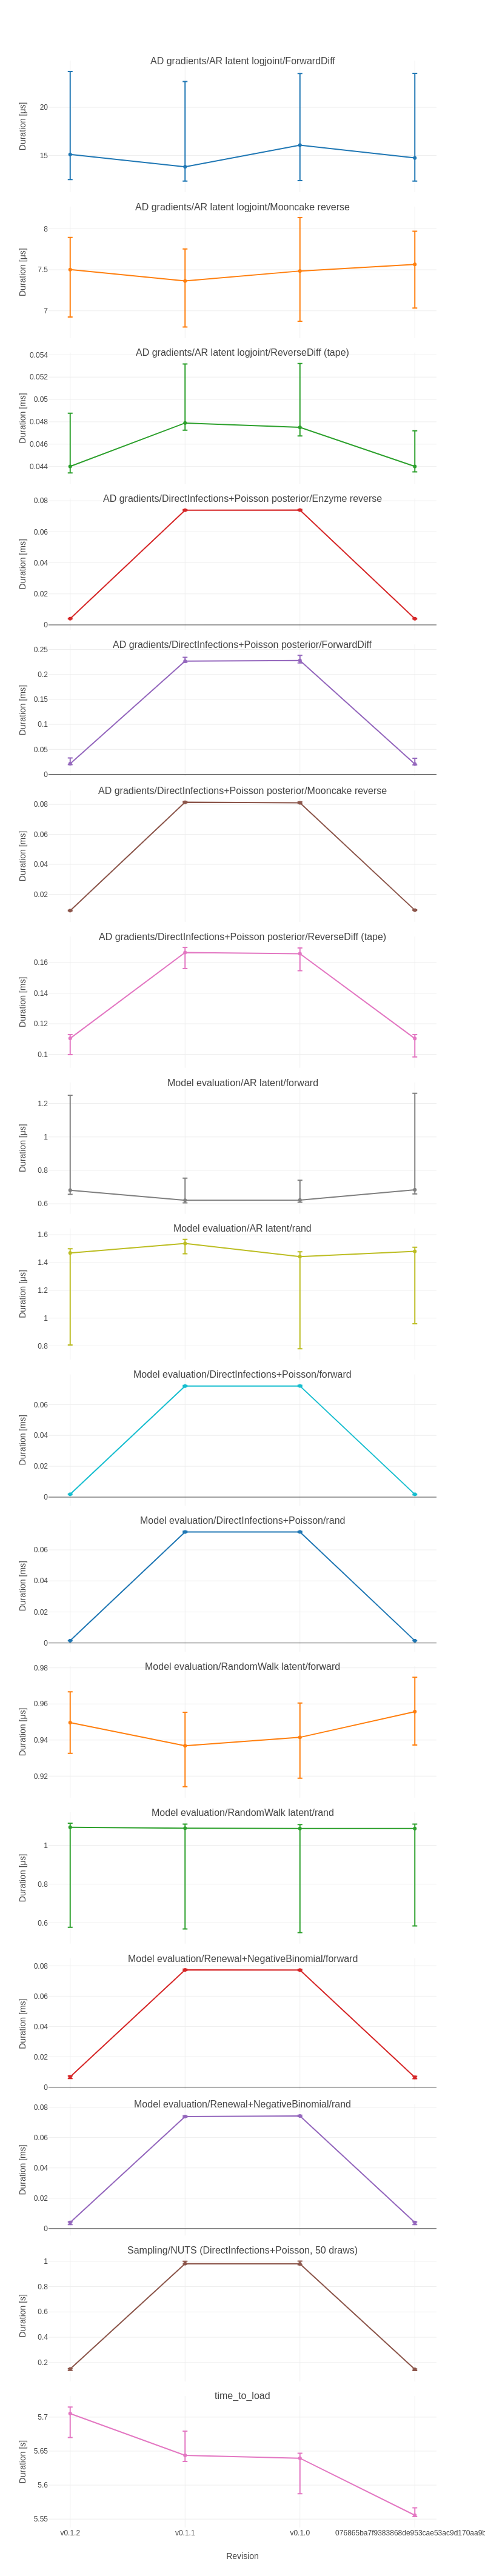
Per-benchmark timelines
<details> <summary>Show 1 plot</summary>
</details>
About these benchmarks
ComposableTuringIDModels tracks the performance of representative modelling operations over time. The suite is a prototype: it covers a small set of representative models rather than exhaustively measuring every component, and the numbers are indicative rather than a guarantee.
Benchmarking reuses the shared tooling in EpiAwarePackageTools.Benchmarks rather than re-implementing a runner or a comparison report. The package owns the suite definition (benchmark/benchmarks.jl); the kit owns running it and turning results into a legible pull-request comment.
What is measured
The suite is a BenchmarkTools.BenchmarkGroup named SUITE, defined in benchmark/benchmarks.jl, with three groups.
Model evaluation — building and evaluating representative models. For each model the suite times a prior draw (
rand, which samples every random variable) and the forward pass (model(), which returns the generated quantities). The models are two latent processes (AR,RandomWalk) and two composedIDModels (DirectInfectionswithPoissonError, andRenewalwithNegativeBinomialError), each turned into a Turing model viaas_turing_model.Sampling — a short NUTS run (50 draws) on a composed
DirectInfections+PoissonErrormodel conditioned on data simulated from its own prior.AD gradients — the gradient of a representative log-density across automatic-differentiation backends (
ForwardDiff,ReverseDiff,Mooncake, andEnzymewhere supported). Results are keyed by scenario and backend so the comparison report folds them into a per-(scenario × backend) matrix.
Running the suite locally
The benchmark/ directory is its own Julia environment. Run the whole suite and save the results with the managed runner, which calls EpiAwarePackageTools.Benchmarks.run_suite:
julia --project=benchmark benchmark/run.jl results.jsonrun_suite uses a short per-benchmark time budget so a full run stays affordable while the minimum-time estimator used in the comparison stays stable. To compare two result files and write a Markdown report, use the managed comparison script, which calls EpiAwarePackageTools.Benchmarks.compare_comment:
julia --project=benchmark benchmark/compare.jl pr.json base.json comment.mdContinuous integration
Two workflows drive benchmarking in CI, both building on the shared kit.
benchmark.yamlruns on pull requests. It benchmarks the pull-request head and the base branch in separate jobs, then posts (and updates) a single comparison comment: a bucketed summary plus collapsed per-benchmark tables split into evaluation and AD-gradient groups.benchmark-history.yamlruns on pushes tomainand on tags. It benchmarks the recent tagged releases plus the current commit with AirspeedVelocity and publishes a timeline to the repository'sbenchmarksbranch. The kit'sasv_comment/flatten_asvhelpers read the same AirspeedVelocity result format when a report is needed.