Renewal model with negative-binomial reporting
The renewal equation is the workhorse of real-time epidemic estimation: it expresses new infections as a function of past infections weighted by the generation interval, scaled by a time-varying reproduction number
This tutorial builds that model from two composed parts — a Renewal infection process that carries an autoregressive latent process for NegativeBinomialError observation model — and fits it to the test-confirmed COVID-19 cases from South Korea that Mishra et al. [2] analysed. The latent
The model
Components
The latent process is a second-order autoregressive model on HierarchicalNormal innovation term, matching Mishra et al. [2]. Strong autocorrelation in the reproduction number is encoded by a first damping prior concentrated near one (
using ComposableTuringIDModels, Distributions, Random, Turing, Mooncake
using ADTypes: AutoMooncake
Random.seed!(1234)

latent = AR(
    damp = [truncated(Normal(0.8, 0.05), 0, 1),
        truncated(Normal(0.1, 0.05), 0, 1)],
    init = [Normal(0.0, 0.2), Normal(0.0, 0.2)],
    ϵ_t = HierarchicalNormal(std = HalfNormal(0.1)))
AR
└─ ϵ_t: HierarchicalNormalThe infection process needs a discrete generation interval. Renewal takes a continuous distribution and discretises it with double interval censoring [9], using CensoredDistributions.jl. Following Mishra et al. [2] we use a Renewal is the only infection model that carries a generation interval, because it is the only one that uses one; it couples that interval to the latent rt slot) and a prior for the initial infections.
renewal = Renewal(; generation_time = Gamma(6.5, 0.62),
    rt = latent, initialisation = Normal(log(1.0), 0.1))
renewal.gen_int
8-element Vector{Float64}:
0.026663134095601098
0.14059778064943768
0.2502660305615845
0.24789569560506872
0.1731751163417783
0.09635404000022221
0.045734375752163825
0.01931382699414364The stored gen_int is a probability vector — the continuous serial interval binned into daily weights that sum to one. Double interval censoring is not the same as evaluating the continuous density at integer days: it accounts for both the primary and secondary events falling anywhere within their days, which shifts and spreads the mass relative to the underlying
sum(renewal.gen_int), length(renewal.gen_int)(0.9999999999999999, 8)The infection process in isolation
Because the renewal model is a model in its own right, it can be exercised on its own — without an observation model — and we can isolate the contribution of the renewal equation by pinning its reproduction-number process to a known trajectory. With the latent folded in, the way to do that is to build a renewal model whose rt slot is a deterministic FixedIntercept latent, giving a constant as_turing_model call that composes into the full model then runs the infection process standalone, returning its infections I_t and the internal latent draw Z_t.
fixed_logR = log(1.4)
renewal_fixed = Renewal(; generation_time = renewal.gen_int,
    rt = FixedIntercept(fixed_logR), initialisation = Normal())
demo = fix(as_turing_model(renewal_fixed, 60), (init_incidence = 0.0,))()
(constant_Rt = round(exp(first(demo.Z_t)), digits = 2),
    grows = demo.I_t[end] > demo.I_t[1])
(constant_Rt = 1.4, grows = true)A constant FixedIntercept latent for a deterministic latent of the desired shape. Nothing here is conditioned on data; the component is inspected in isolation before it is assembled into the full model with its sampled
Reported cases are overdispersed counts of the latent infections. The prior is placed on the cluster factor
obs = NegativeBinomialError(cluster_factor = HalfNormal(0.1))IDModel assembles the two parts — the renewal infection process (which already carries the latent
model = IDModel(renewal, obs)IDModel
├─ infection: Renewal
│ └─ rt: AR
│ └─ ϵ_t: HierarchicalNormal
└─ observation: NegativeBinomialErrorBefore fitting, the composed model is also a prior simulator: passing missing observations makes as_turing_model return generated quantities — the reported cases generated_y_t, the latent infections I_t, and the latent process Z_t — instead of conditioning on data. That is the mechanism used for the prior checks above; here we go straight to real data.
The data
Mishra et al. [2] fit this model to daily test-confirmed COVID-19 cases in South Korea over the first wave of 2020. The series is stored with the docs and read with CSV/DataFrames.
using CSV, DataFrames
datapath = joinpath(pkgdir(ComposableTuringIDModels),
    "docs", "src", "tutorials", "data", "south_korea_data.csv")
south_korea = CSV.read(datapath, DataFrame)
first(south_korea, 5)| Row | Column1 | date | cases_new | deaths_new |
|---|---|---|---|---|
| Int64 | Date | Int64 | Int64 | |
| 1 | 1 | 2019-12-31 | 0 | 0 |
| 2 | 2 | 2020-01-01 | 0 | 0 |
| 3 | 3 | 2020-01-02 | 0 | 0 |
| 4 | 4 | 2020-01-03 | 0 | 0 |
| 5 | 5 | 2020-01-04 | 0 | 0 |
We fit the growth-and-decline window of the first wave, matching the span used by Mishra et al. [2], and take the reported cases over it as the observed series.
tspan = (45, 80)
y_obs = south_korea.cases_new[first(tspan):last(tspan)]
n = length(y_obs)
(n = n, total_cases = sum(y_obs),
    from = south_korea.date[first(tspan)], to = south_korea.date[last(tspan)])
(n = 36, total_cases = 8537, from = Dates.Date("2020-02-13"), to = Dates.Date("2020-03-19"))Fit
Conditioning on the observed counts and sampling with NUTS recovers the posterior. We draw two chains in parallel with MCMCThreads() so the posterior is well resolved and the cross-chain
posterior = as_turing_model(model, y_obs, n)
chain = sample(
    posterior, NUTS(0.95; adtype = AutoMooncake(; config = nothing)),
    MCMCThreads(), 250, 2; progress = false)
┌ Info: Found initial step size
└ ϵ = 0.0015625
┌ Info: Found initial step size
└ ϵ = 0.003125
┌ Warning: There were 3 divergent transitions. Consider reparameterising your model or using a smaller step size. For adaptive samplers such as NUTS and HMCDA, consider increasing `target_accept`.
└ @ Turing.Inference ~/.julia/packages/Turing/WteH7/src/mcmc/hmc.jl:483
┌ Warning: There were 3 divergent transitions. Consider reparameterising your model or using a smaller step size. For adaptive samplers such as NUTS and HMCDA, consider increasing `target_accept`.
└ @ Turing.Inference ~/.julia/packages/Turing/WteH7/src/mcmc/hmc.jl:483Sampling returns a chain whose parameters are namespaced by the component slot that samples them, so a prior's inner variables never collide across the model. sample returns a FlexiChains chain, which summarystats summarises directly — no conversion step — giving point estimates and their uncertainty alongside the effective sample size and damp_AR[1]), the innovation scale std), and the observation cluster factor cluster_factor) are all identified from the observed South Korean series:
using MCMCChains
summarystats(chain)╭─FlexiSummary (9 statistics) ─────────────────────────────────────────────────╮
│ iter collapsed │
│ chain collapsed │
│ ↓ stat = [mean, std, mcse, ess_bulk, ess_tail, rhat, q5, q50, q95] │
│ │
│ Parameters (41) ── AbstractPPL.VarName │
│ Float64 ar_init[1], ar_init[2], damp_AR[1], damp_AR[2], std, ϵ_t[1], │
│ ϵ_t[2], ϵ_t[3], ϵ_t[4], ϵ_t[5], ϵ_t[6], ϵ_t[7], ϵ_t[8], ϵ_t[9], │
│ ϵ_t[10], ϵ_t[11], ϵ_t[12], ϵ_t[13], ϵ_t[14], ϵ_t[15], ϵ_t[16], │
│ ϵ_t[17], ϵ_t[18], ϵ_t[19], ϵ_t[20], ϵ_t[21], ϵ_t[22], ϵ_t[23], │
│ ϵ_t[24], ϵ_t[25], ϵ_t[26], ϵ_t[27], ϵ_t[28], ϵ_t[29], ϵ_t[30], │
│ ϵ_t[31], ϵ_t[32], ϵ_t[33], ϵ_t[34], init_incidence, │
│ cluster_factor │
│ │
│ Extras (14) │
│ Float64 n_steps, is_accept, acceptance_rate, log_density, │
│ hamiltonian_energy, hamiltonian_energy_error, │
│ max_hamiltonian_energy_error, tree_depth, numerical_error, │
│ step_size, nom_step_size, logprior, loglikelihood, logjoint │
│ │
│ Summary │
│ param mean std mcse ess_bulk ess_tail rhat … │
│ ar_init[1] 0.0241 0.2044 0.0064 1021.9261 289.3026 0.9983 … │
│ ar_init[2] -0.0053 0.1786 0.0070 658.8058 385.3740 1.0068 … │
│ damp_AR[1] 0.8162 0.0410 0.0030 187.5200 218.6860 0.9988 … │
│ damp_AR[2] 0.0818 0.0411 0.0052 59.7863 51.3603 1.0025 … │
│ std 0.4195 0.0527 0.0056 81.3789 168.6317 1.0413 … │
│ ϵ_t[1] 0.4637 0.8546 0.0881 100.9375 119.3474 1.0070 … │
│ ϵ_t[2] 0.9851 0.7919 0.0719 122.4729 204.0446 1.0174 … │
│ ϵ_t[3] 1.2117 0.8570 0.0842 106.0349 96.0334 1.0076 … │
│ ϵ_t[4] 1.1032 0.8522 0.0903 88.0828 170.5546 1.0024 … │
│ ϵ_t[5] 2.5384 0.8414 0.0961 77.6998 113.8988 1.0050 … │
│ ϵ_t[6] 1.6305 0.6682 0.0488 194.3839 281.0318 0.9993 … │
│ ϵ_t[7] 0.8513 0.6129 0.0546 122.9120 142.1556 1.0179 … │
│ ϵ_t[8] 0.7227 0.5589 0.0540 109.0118 161.7528 1.0119 … │
│ ϵ_t[9] -0.6171 0.5290 0.0508 110.6514 168.0173 1.0154 … │
│ ϵ_t[10] -2.2310 0.5459 0.0459 129.6825 239.1335 1.0039 … │
│ ϵ_t[11] -1.6340 0.5574 0.0525 127.3948 81.2469 1.0175 … │
│ ϵ_t[12] 0.4891 0.5471 0.1034 48.4277 34.0486 1.1197 … │
│ ϵ_t[13] 1.1008 0.4276 0.0372 149.4348 157.6252 1.0144 … │
│ ϵ_t[14] -0.0019 0.3837 0.0215 321.9883 209.6166 1.0155 … │
│ ϵ_t[15] 1.2050 0.3885 0.0416 122.5384 251.0441 1.0258 … │
│ ϵ_t[16] -1.0646 0.4039 0.0522 81.9447 54.9651 1.0212 … │
│ ϵ_t[17] -0.3930 0.3674 0.0233 262.3004 161.5926 1.0375 … │
│ ϵ_t[18] -0.7806 0.3588 0.0210 279.4157 320.6063 1.0177 … │
│ ϵ_t[19] -0.6659 0.4057 0.0311 218.0079 116.5552 1.0339 … │
│ ϵ_t[20] -0.5632 0.3925 0.0321 221.1487 126.5661 1.0294 … │
│ ϵ_t[21] 0.2225 0.3980 0.0286 244.4907 92.6167 1.0348 … │
│ ϵ_t[22] -0.1064 0.3522 0.0275 230.5586 134.7165 1.0320 … │
│ ϵ_t[23] -0.4911 0.4036 0.0308 213.0172 101.2525 1.0587 … │
│ ϵ_t[24] -0.9136 0.3999 0.0282 278.8513 89.8392 1.0336 … │
│ ϵ_t[25] -1.3450 0.4566 0.0368 183.1375 96.2466 1.0262 … │
│ ϵ_t[26] 0.9760 0.4784 0.0715 73.6551 33.6547 1.0413 … │
│ ϵ_t[27] -1.0221 0.5012 0.0585 108.0127 51.1293 1.0306 … │
│ ϵ_t[28] -0.0381 0.4147 0.0217 379.0928 322.4902 1.0098 … │
│ ϵ_t[29] 0.1476 0.4707 0.0363 210.4715 47.5624 1.0089 … │
│ ϵ_t[30] -0.2608 0.4526 0.0369 177.6055 86.4624 1.0105 … │
│ ϵ_t[31] 0.2057 0.4574 0.0281 295.7692 112.8709 1.0073 … │
│ ϵ_t[32] 0.5771 0.4422 0.0246 332.3425 210.9724 1.0103 … │
│ ϵ_t[33] 0.5936 0.4653 0.0346 206.0052 176.2790 1.0105 … │
│ ϵ_t[34] 1.2809 0.4385 0.0280 256.9513 171.4893 1.0053 … │
│ init_incide… -0.0353 0.1020 0.0046 480.7345 398.2073 1.0040 … │
│ cluster_fac… 0.0977 0.0720 0.0187 16.0141 109.2943 1.1027 … │
╰──────────────────────────────────────────────────────────────────────────────╯Prior versus posterior
Before reading the trajectories it is worth asking what the data taught us. Sampling the same model with Prior — ignoring the observations — gives a prior draw over the same parameters, and overlaying it on the posterior shows which parameters moved. We load a Makie backend and PairPlots.jl; the FlexiChains PairPlots extension turns a chain (subset to a few keys with chain[[...]]) into a PairPlots.Series, so prior and posterior overlay on one corner plot.
using CairoMakie, PairPlots

prior_chain = sample(posterior, Prior(), 1000; progress = false)
pp_keys = [@varname(damp_AR), @varname(std),
    @varname(cluster_factor), @varname(init_incidence)]
pairplot(
    PairPlots.Series(chain[pp_keys]; label = "posterior"),
    PairPlots.Series(prior_chain[pp_keys]; label = "prior"))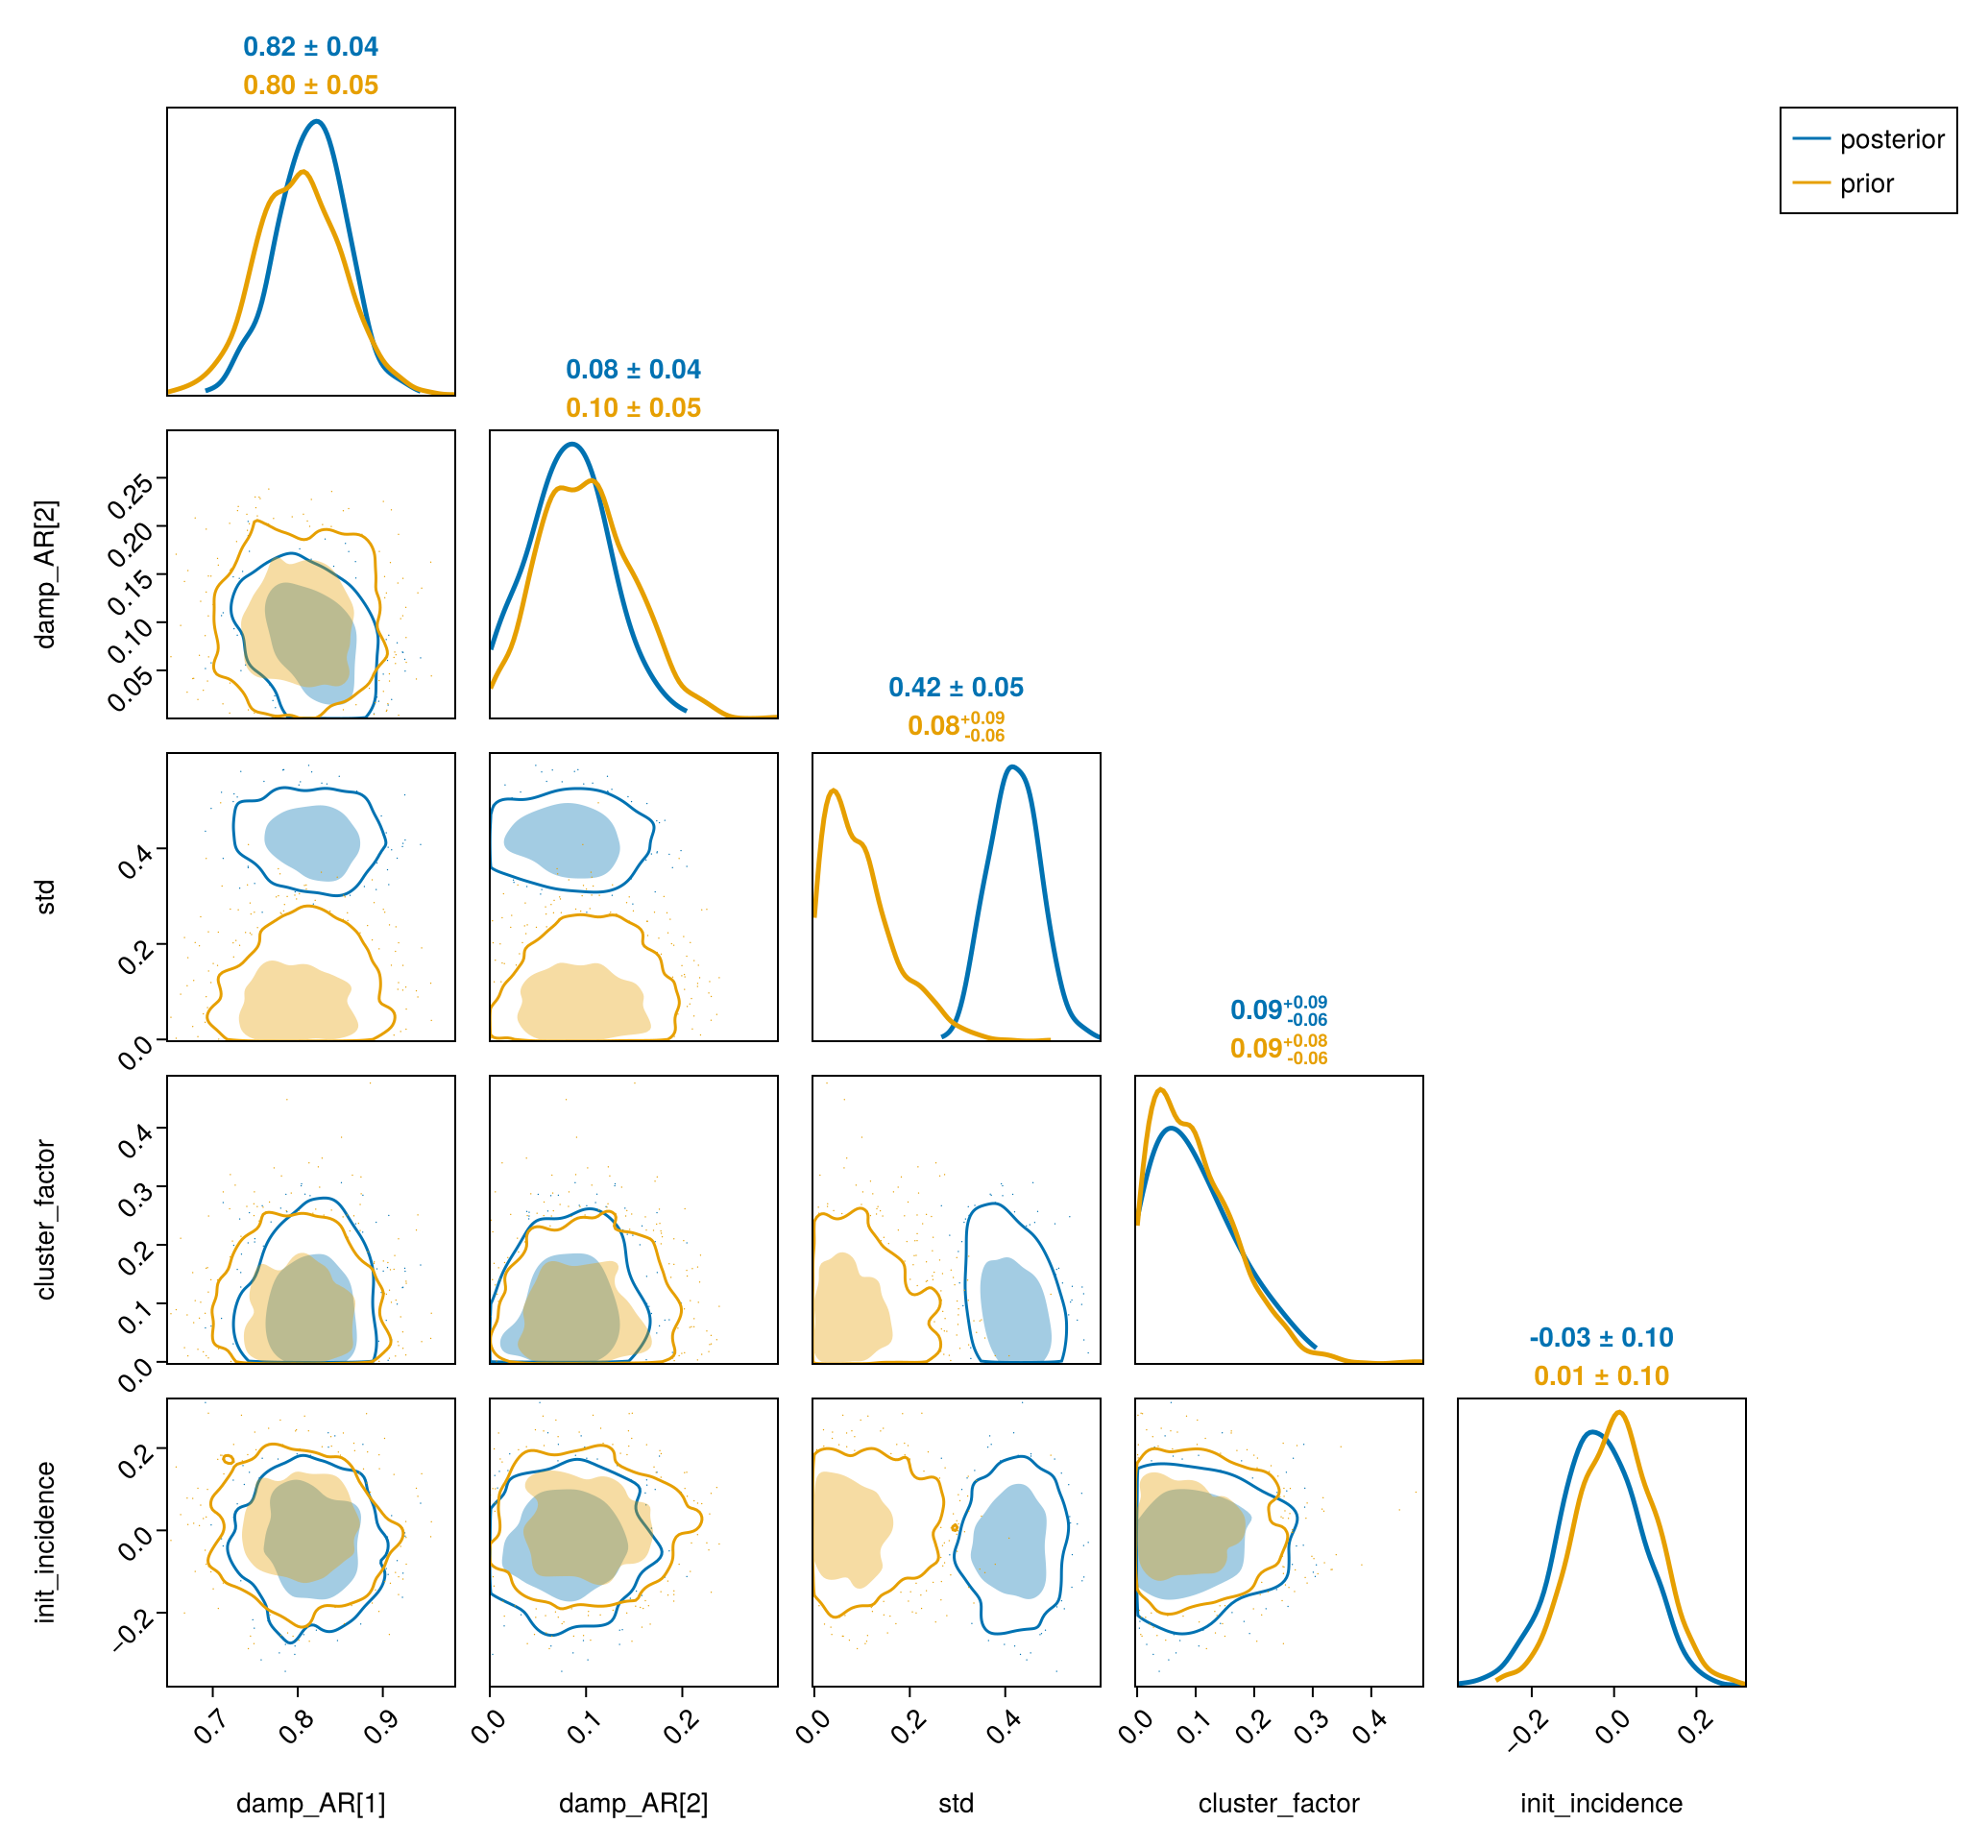
The innovation scale std) is sharply updated away from its prior — the data are informative about how much damp_AR), the cluster factor and the initial infections stay closer to their priors on this short window.
Posterior trajectories
The reproduction number generated_observables re-runs the fitted model over the chain to recover the latent predict on the same model with the observations set to missing.
A couple of small helpers reduce the per-draw trajectories to credible bands and draw a median line with 50% and 95% ribbons.
Stack the per-draw
gens = vec(generated_observables(posterior, y_obs, chain).generated)
Rt = credible_bands(reduce(hcat, (exp.(g.Z_t) for g in gens)))

pred = predict(as_turing_model(model, fill(missing, n), n), chain)
yt = predictive_bands(pred, n)

fig = Figure(; size = (760, 620))
ax1 = Axis(fig[1, 1]; ylabel = "Reproduction number Rₜ")
ci_ribbon!(ax1, 1:size(Rt, 1), Rt; color = :purple, label = "posterior median")
hlines!(ax1, [1.0]; color = :grey, linestyle = :dash)
axislegend(ax1; position = :rt)
ax2 = Axis(fig[2, 1]; xlabel = "Day", ylabel = "Reported cases")
ci_ribbon!(ax2, 1:size(yt, 1), yt; color = :teal,
    label = "posterior predictive")
scatter!(ax2, 1:n, y_obs; color = :black, markersize = 7, label = "observed")
axislegend(ax2; position = :lt)
fig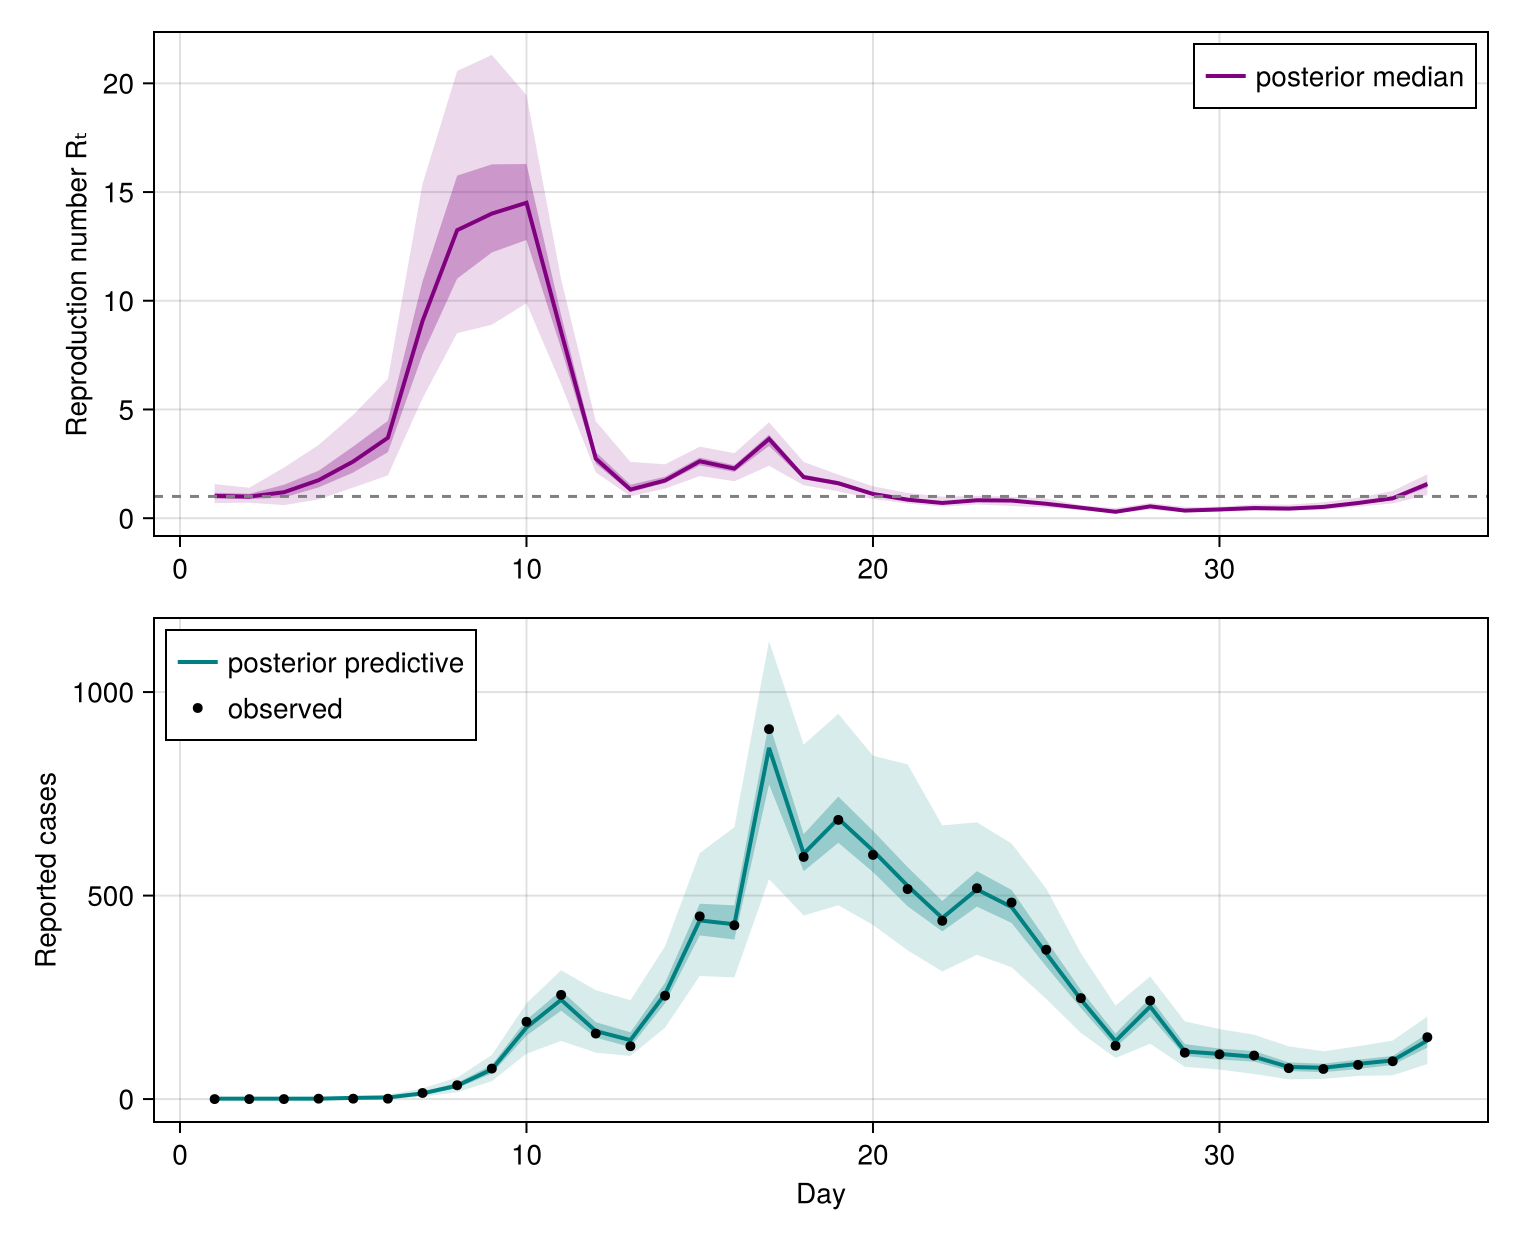
The posterior-predictive band tracks the observed South Korean series closely, and the
Forecasting the next weeks
The same fitted model forecasts out of sample in one call. Because the latent AR process is non-centred, forecast carries each posterior draw forward — holding the fitted parameters and the in-sample
h = 14
fc = forecast(model, y_obs, chain, h)
size(fc)
(250, 2)The returned chain carries the predicted
# Multi-level CI band quantiles: 90%, 60%, 30% + median
FC_CI_QS = [0.05, 0.2, 0.35, 0.5, 0.65, 0.8, 0.95]

# Draw three nested CI ribbons with the median line
function multi_ci_ribbon!(ax, ts, bands; color, label)
    keep = findall(!ismissing, view(bands, :, 4))
    x, b = ts[keep], Float64.(bands[keep, :])
    # 90% CI (cols 1, 7)
    band!(ax, x, b[:, 1], b[:, 7]; color = (color, 0.1))
    # 60% CI (cols 2, 6)
    band!(ax, x, b[:, 2], b[:, 6]; color = (color, 0.25))
    # 30% CI (cols 3, 5)
    band!(ax, x, b[:, 3], b[:, 5]; color = (color, 0.5))
    # median (col 4)
    lines!(ax, x, b[:, 4]; color = color, linewidth = 2, label = label)
end

# Multi-level credible bands for the forecast
fc_bands = credible_bands(reduce(vcat,
    (permutedims(vec(fc[@varname(y_t[i])])) for i in (n + 1):(n + h)));
    qs = FC_CI_QS)

# Sample 100 random forecast trajectories
n_draws = length(vec(fc[@varname(y_t[n + 1])]))
ntraj = min(100, n_draws)
sample_idx = rand(1:n_draws, ntraj)
trajectories = reduce(hcat,
    [[vec(fc[@varname(y_t[i])])[idx] for i in (n + 1):(n + h)] for idx in sample_idx])

fig_fc = Figure(; size = (760, 360))
axf = Axis(fig_fc[1, 1]; xlabel = "Day", ylabel = "Reported cases",
    yscale = log10)
scatter!(axf, 1:n, y_obs; color = :black, markersize = 7, label = "observed")
# Faint individual forecast trajectories
for idx in 1:ntraj
    lines!(axf, (n + 1):(n + h), max.(trajectories[:, idx], 1);
        color = (:teal, 0.08), linewidth = 0.5)
end
# Multi-level CI bands (offset to keep log10 scale safe at zero)
multi_ci_ribbon!(axf, (n + 1):(n + h), max.(fc_bands, 1); color = :teal,
    label = "forecast")
vlines!(axf, [n + 0.5]; color = :grey, linestyle = :dash)
axislegend(axf; position = :lt)
fig_fc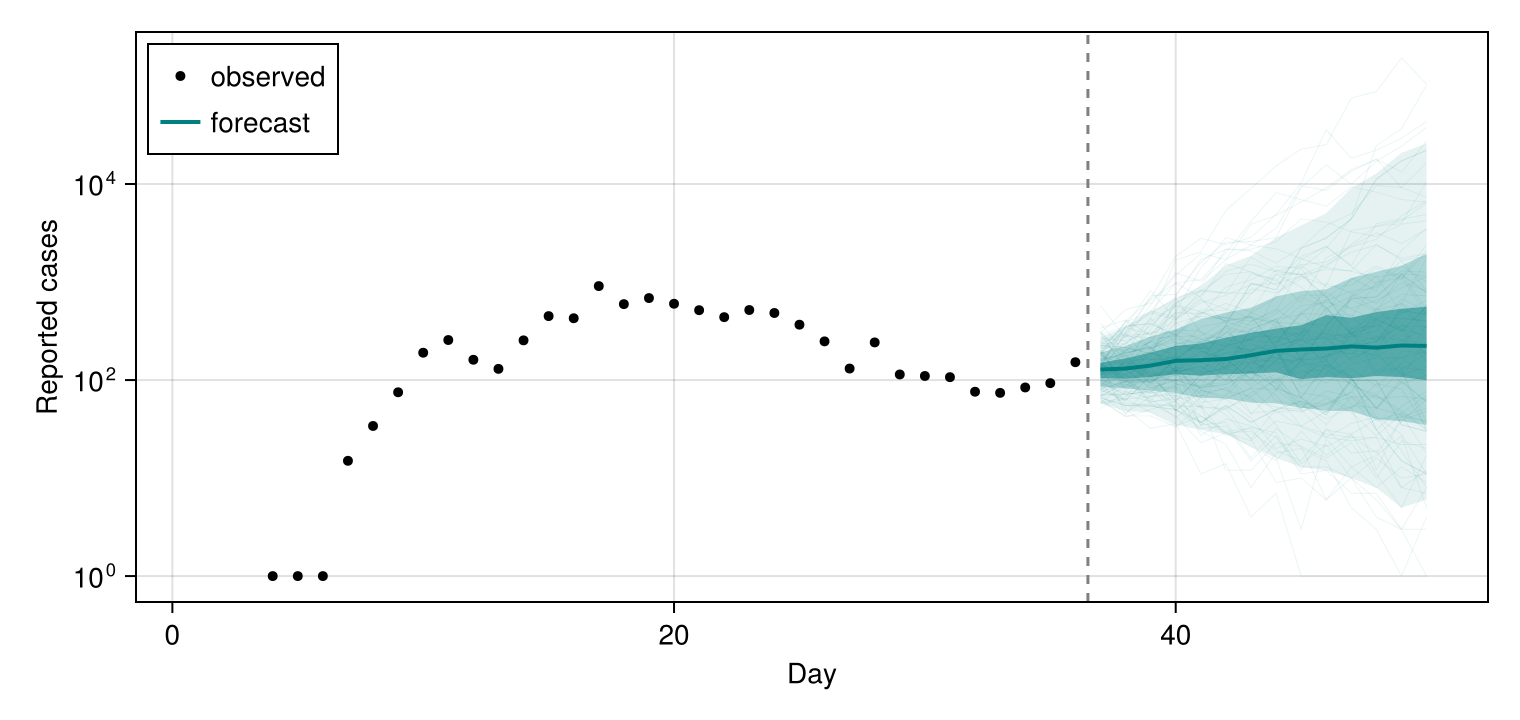
Swap a component
Because the parts share one interface, an alternative observation assumption is a one-line change. Swapping the negative-binomial reporting for a PoissonError leaves the renewal infection process — and its latent
poisson_model = IDModel(renewal, PoissonError())
length(rand(as_turing_model(poisson_model, fill(missing, n), n)))41References
A. Cori, N. M. Ferguson, C. Fraser and S. Cauchemez. A new framework and software to estimate time-varying reproduction numbers during epidemics. American Journal of Epidemiology 178, 1505–1512 (2013).
S. Mishra, T. Berah, T. A. Mellan, H. J. Unwin, M. A. Vollmer, K. V. Parag, A. Gandy, S. Flaxman and S. Bhatt. On the derivation of the renewal equation from an age-dependent branching process: an epidemic modelling perspective, arXiv preprint arXiv:2006.16487 (2020).
K. Charniga, S. W. Park, A. R. Akhmetzhanov, A. Cori, J. Dushoff, S. Funk and others. Best practices for estimating and reporting epidemiological delay distributions of infectious diseases. PLoS Computational Biology 20, e1012520 (2024).